Tokonomics
Track, cap, and optimize AI API costs across every provider

Details
- Follow on
- Categories
- Target Audience
- Pricing
- Freemium
Discovery signals
How AI and people discover Tokonomics on PeerPush
- ChatGPT
- Perplexity
- Claude
- +3 other AI crawlers
Reads by these AI engines
Crawlers behind these engines read this listing on PeerPush.About Tokonomics
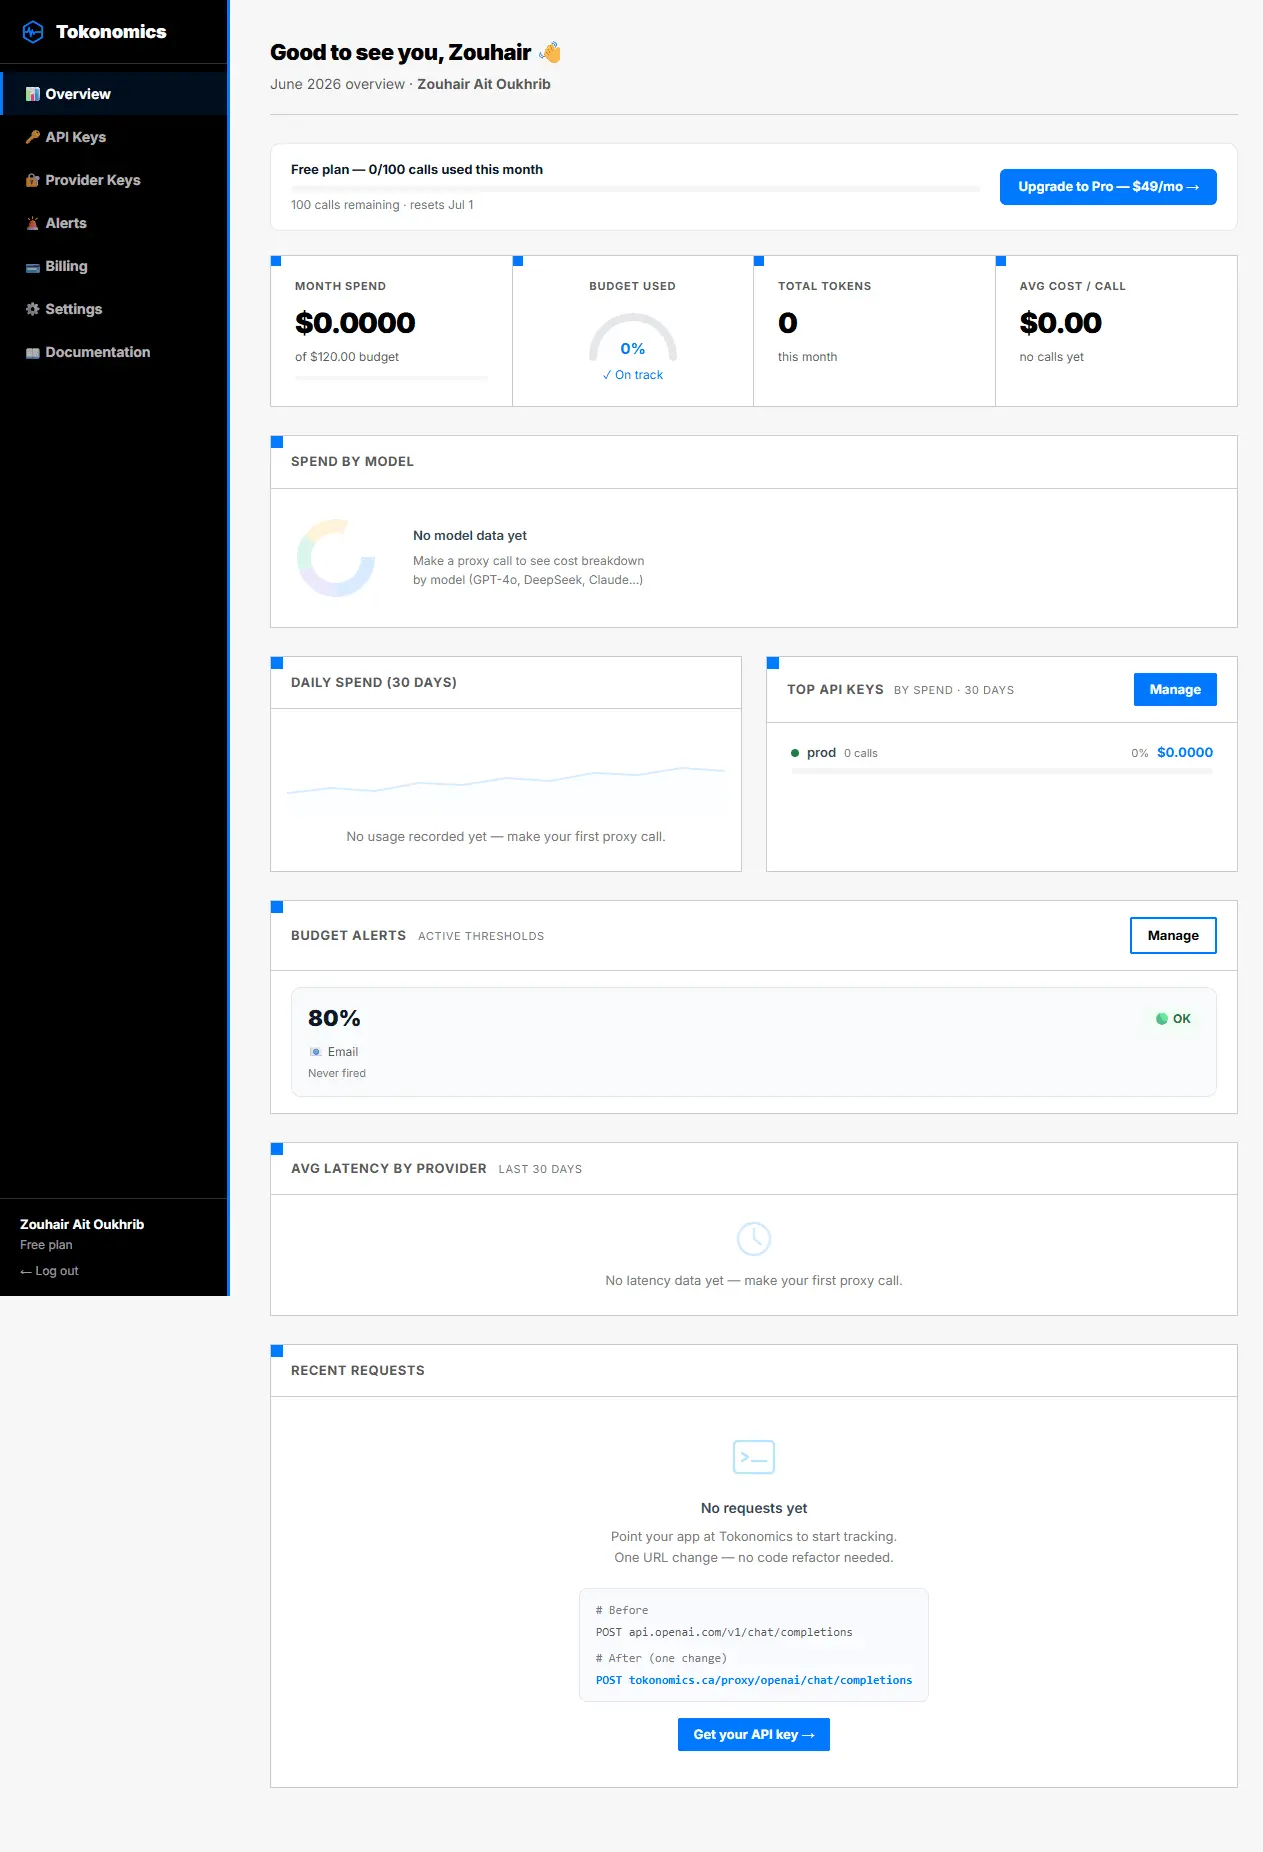
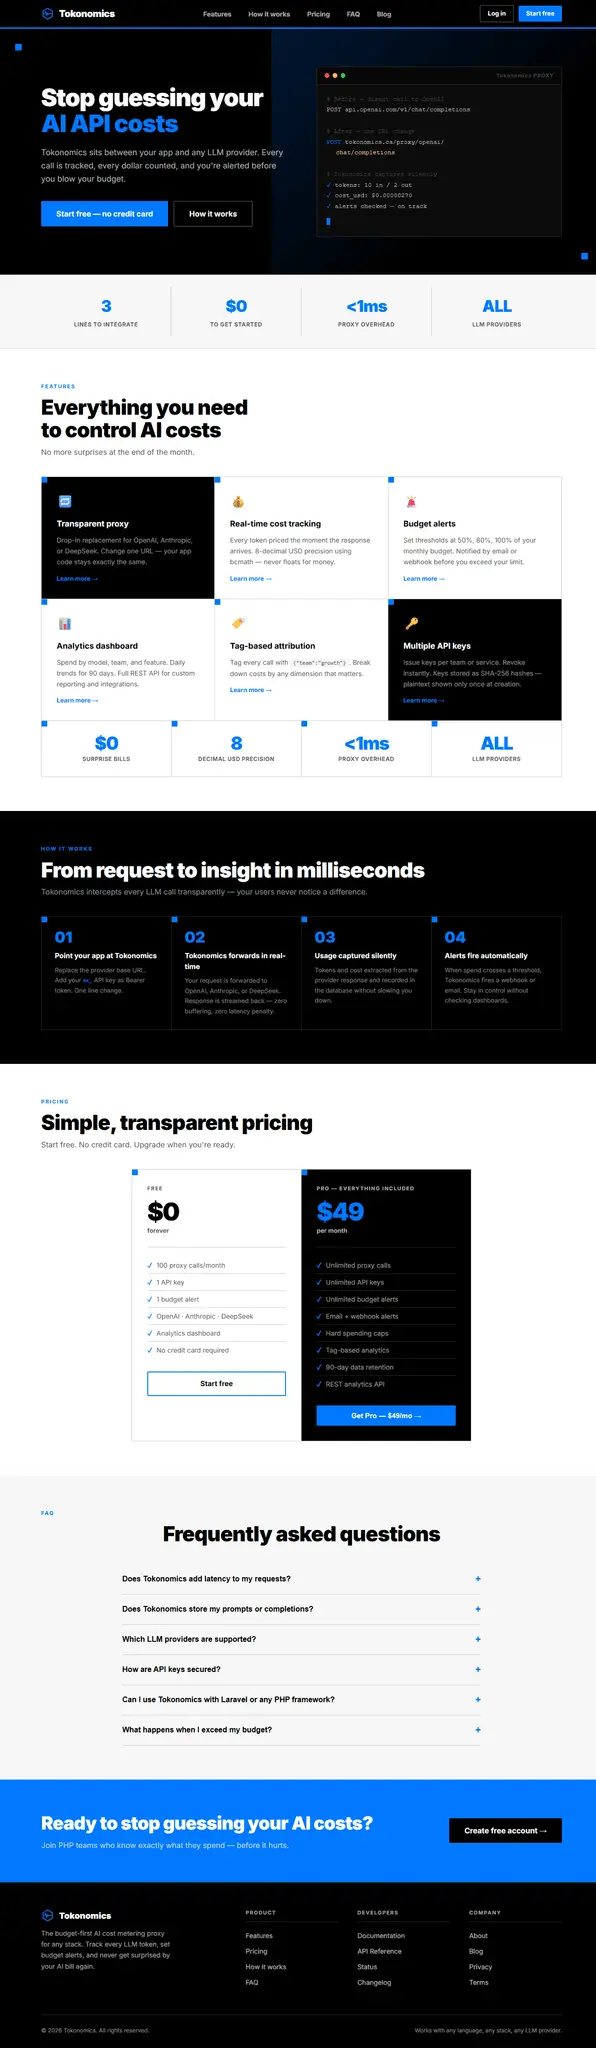
Tokonomics is an API proxy that sits between your application and any LLM provider — OpenAI, Anthropic, DeepSeek, Google Gemini, xAI, and any OpenAI-compatible API. Change one URL, keep your existing code, and get complete cost visibility. The problem: AI API bills are unpredictable. Teams discover $500+ overruns only when the invoice arrives. There's no built-in way to track cost per feature, per team, or per customer across multiple LLM providers. How it works: Route your LLM calls through Tokonomics (one URL change — no SDK, no code rewrite). The proxy forwards requests to the upstream provider, streams responses back unchanged, and records every call — tokens, cost, model, latency. What you get: - Real-time cost dashboard with daily spend charts, model breakdown, and budget gauge - Budget alerts via email, Slack, or Microsoft Teams when spending hits 70%, 90%, or any custom threshold - Hard spending caps that block API calls when the monthly budget is exceeded — no more surprise bills - Per-feature cost tracking using custom tags (X-Metering-Tags header) — see what your chatbot costs vs your summarizer - AI cost optimization reports that detect expensive patterns: wrong model choice, output token waste, cost spikes - Support for 9+ LLM providers in one unified dashboard - Prompt cache tracking with per-provider discount calculation (OpenAI 50%, Anthropic 90%, Gemini 75%) - Works with any language, any framework, any HTTP client — PHP, Python, Node.js, Go, Ruby, curl Built for SaaS founders, agencies, and automation builders (n8n, Make, Zapier, Flowise, Bubble) who need to know exactly what their AI features cost before the invoice arrives. Free plan: 100 API calls/month, 1 budget alert, 30-day retention. Pro plan: $49/month — unlimited calls, unlimited alerts, 90-day retention, hard caps, Slack/Teams alerts, cost optimization reports. 31ms average proxy overhead (3.6% on a typical LLM call). Open benchmarks published at tokonomics.ca/blog/proxy-latency-benchmark-2026.
Screenshots
Reviews (0)
No reviews yet. Be the first to rate this product!
Comments (0)
No comments yet. Be the first to share your thoughts!