VCL VibeBench
Open AI model benchmark you can fork and re-run yourself.

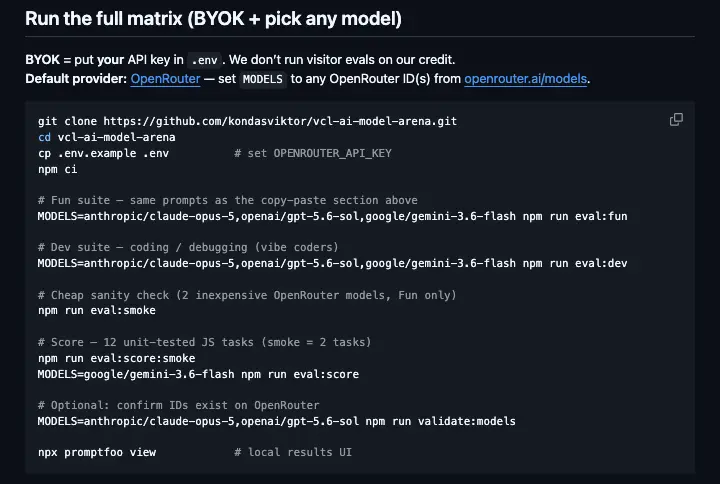
git clone https://github.com/kondasviktor/vcl-ai-model-arena.git && cd vcl-ai-model-arena && cp .env.example .env && npm ciDetails
- Categories
- Use Cases
- Target Audience
- Pricing
- Free
Discovery signals
How AI and people discover VCL VibeBench on PeerPush
About VCL VibeBench
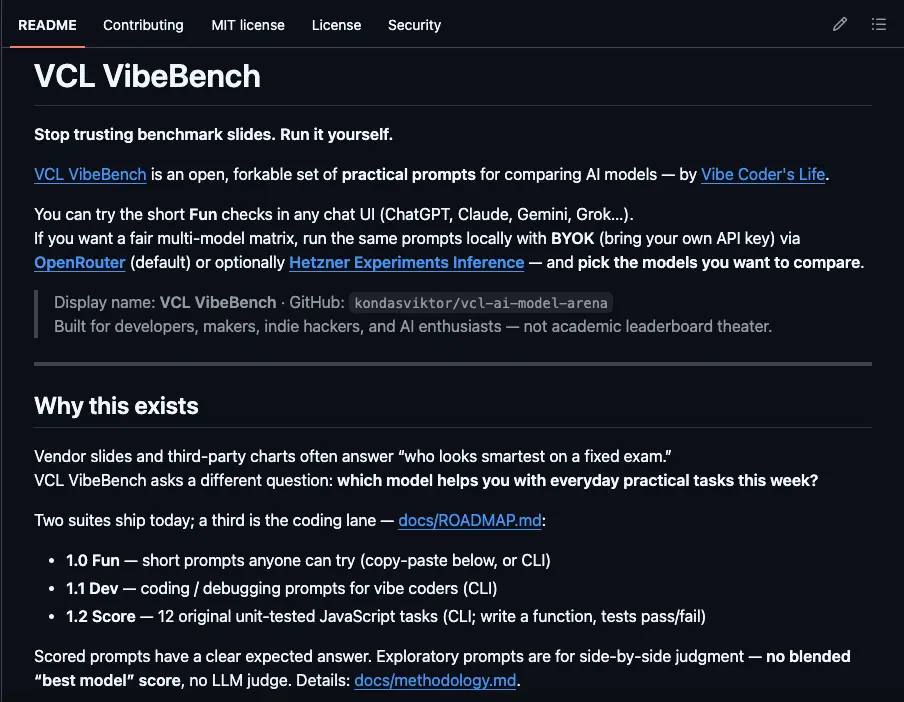
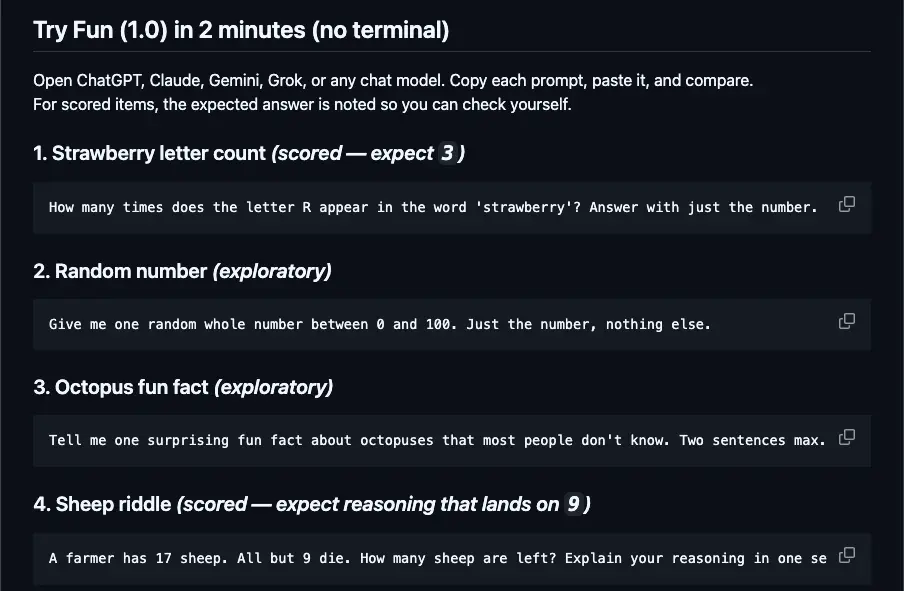
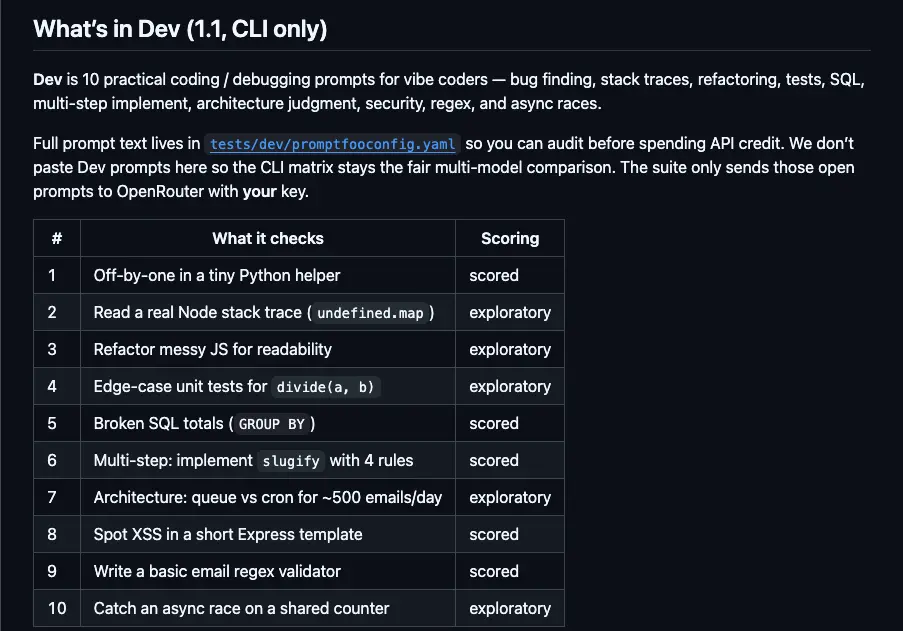
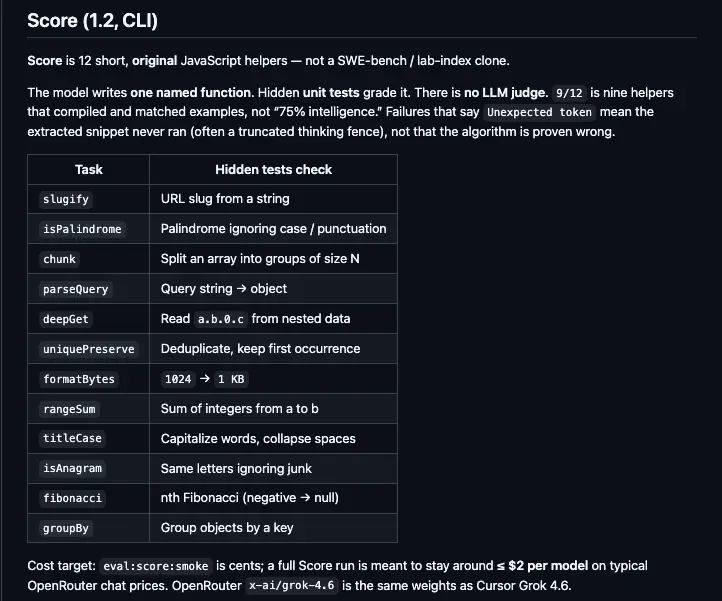
VCL VibeBench is an open, forkable set of practical prompts for comparing AI models — built by Vibe Coder's Life. Stop trusting vendor slides. Run the same prompts yourself with your own API key and pick the models you want to compare. Three suites ship today: 1.0 Fun — 10 short prompts anyone can try by copy-pasting into ChatGPT, Claude, Gemini, Grok, or any chat UI. No terminal, no key required. Scored items have a clear expected answer; exploratory prompts are for side-by-side judgment. 1.1 Dev — 10 practical coding and debugging prompts for vibe coders (CLI). Bug hunts, stack traces, SQL, XSS, regex, architecture judgment — scored and exploratory, no LLM judge. 1.2 Score — 12 original JavaScript helper functions. The model writes one named function; hidden unit tests grade it. Pass/fail only — no LLM judge, not a SWE-bench or lab-index clone. A Score run for a full model costs around $2 or less on typical OpenRouter prices; a 2-task smoke check is cents. How it works: Clone the repo, set your own OpenRouter API key (BYOK), pick any model IDs, and run npm run eval:fun / eval:dev / eval:score. No blended "best model" number across suites. Scored prompts use deterministic asserts. Exploratory prompts are for qualitative side-by-side comparison. Results are committed as JSON + metadata — reproducible and forkable. Optional: run against Hetzner Experiments Inference (EU-hosted open weights) with PROVIDER=hetzner. Maintainer result (Aug 2026): OpenRouter x-ai/grok-4.6 (same weights as Cursor Grok 4.6) recorded 9/12 on Score. Three fails were syntax errors from a truncated thinking fence — the finished functions re-grade 12/12. Fun + Dev results: six frontier models (Claude Opus 4.8, GPT-5.6 Sol, Gemini 3.6 Flash, Grok 4.5, Kimi K3, Fable 5), July 2026. Open source: code MIT, prompts CC BY 4.0. Solo-maintained. Star, fork, and bring your own key. GitHub: github.com/kondasviktor/vcl-ai-model-arena Write-ups: vibecoderslife.com
Screenshots
Reviews (0)
No reviews yet. Be the first to rate this product!
Comments (0)
No comments yet. Be the first to share your thoughts!