Tokenwise
A smart LLM proxy that shows where you're overpaying

Details
- Follow on
- @toflou
- Categories
- AIAnalytics & Monitoring
- Target Audience
- DevelopersFounders & CEOsAI Startups
- Pricing
- Freemium
- Platforms
- Web
Discovery signals
How AI and people discover Tokenwise on PeerPush
- ChatGPT
- Perplexity
- Claude
- +4 other AI crawlers
Reads by these AI engines
Crawlers behind these engines read this listing on PeerPush.About Tokenwise
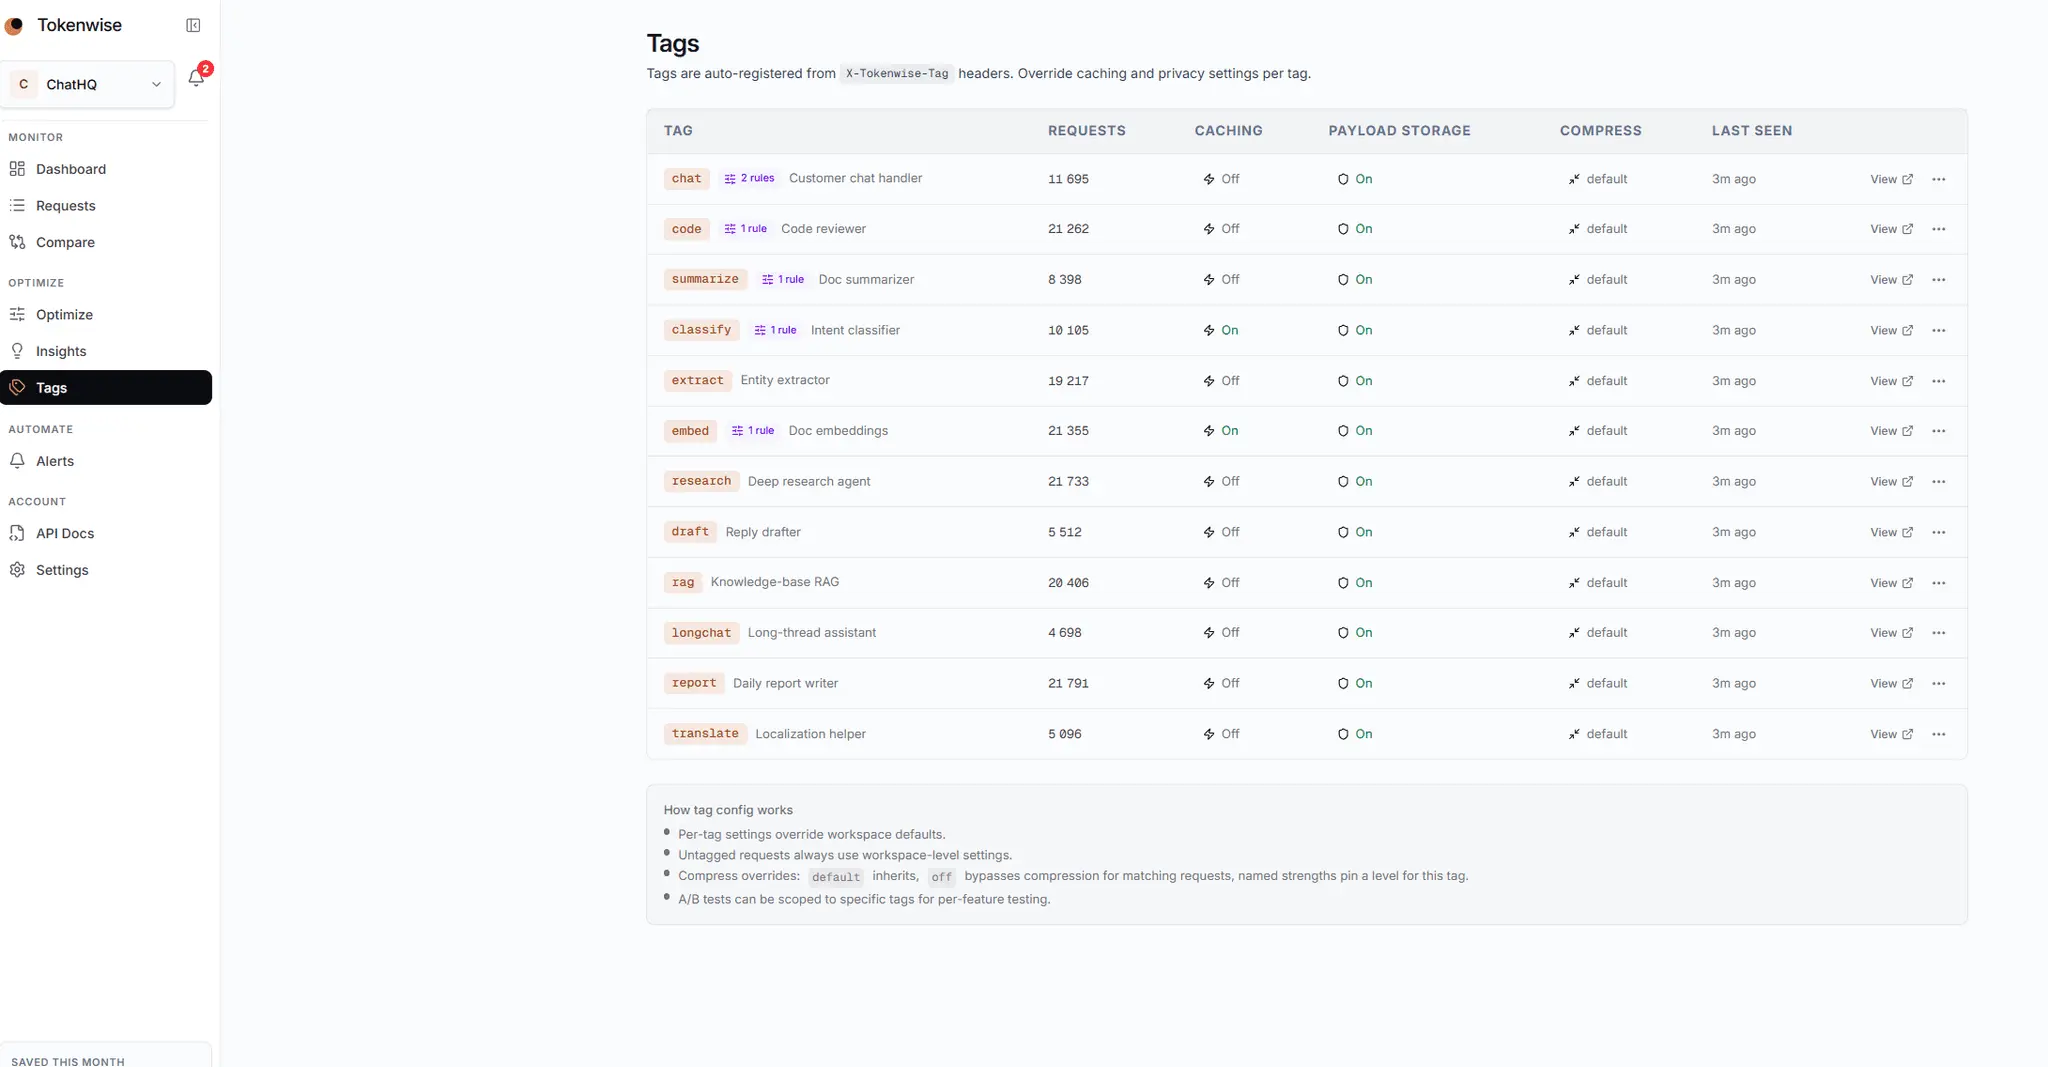
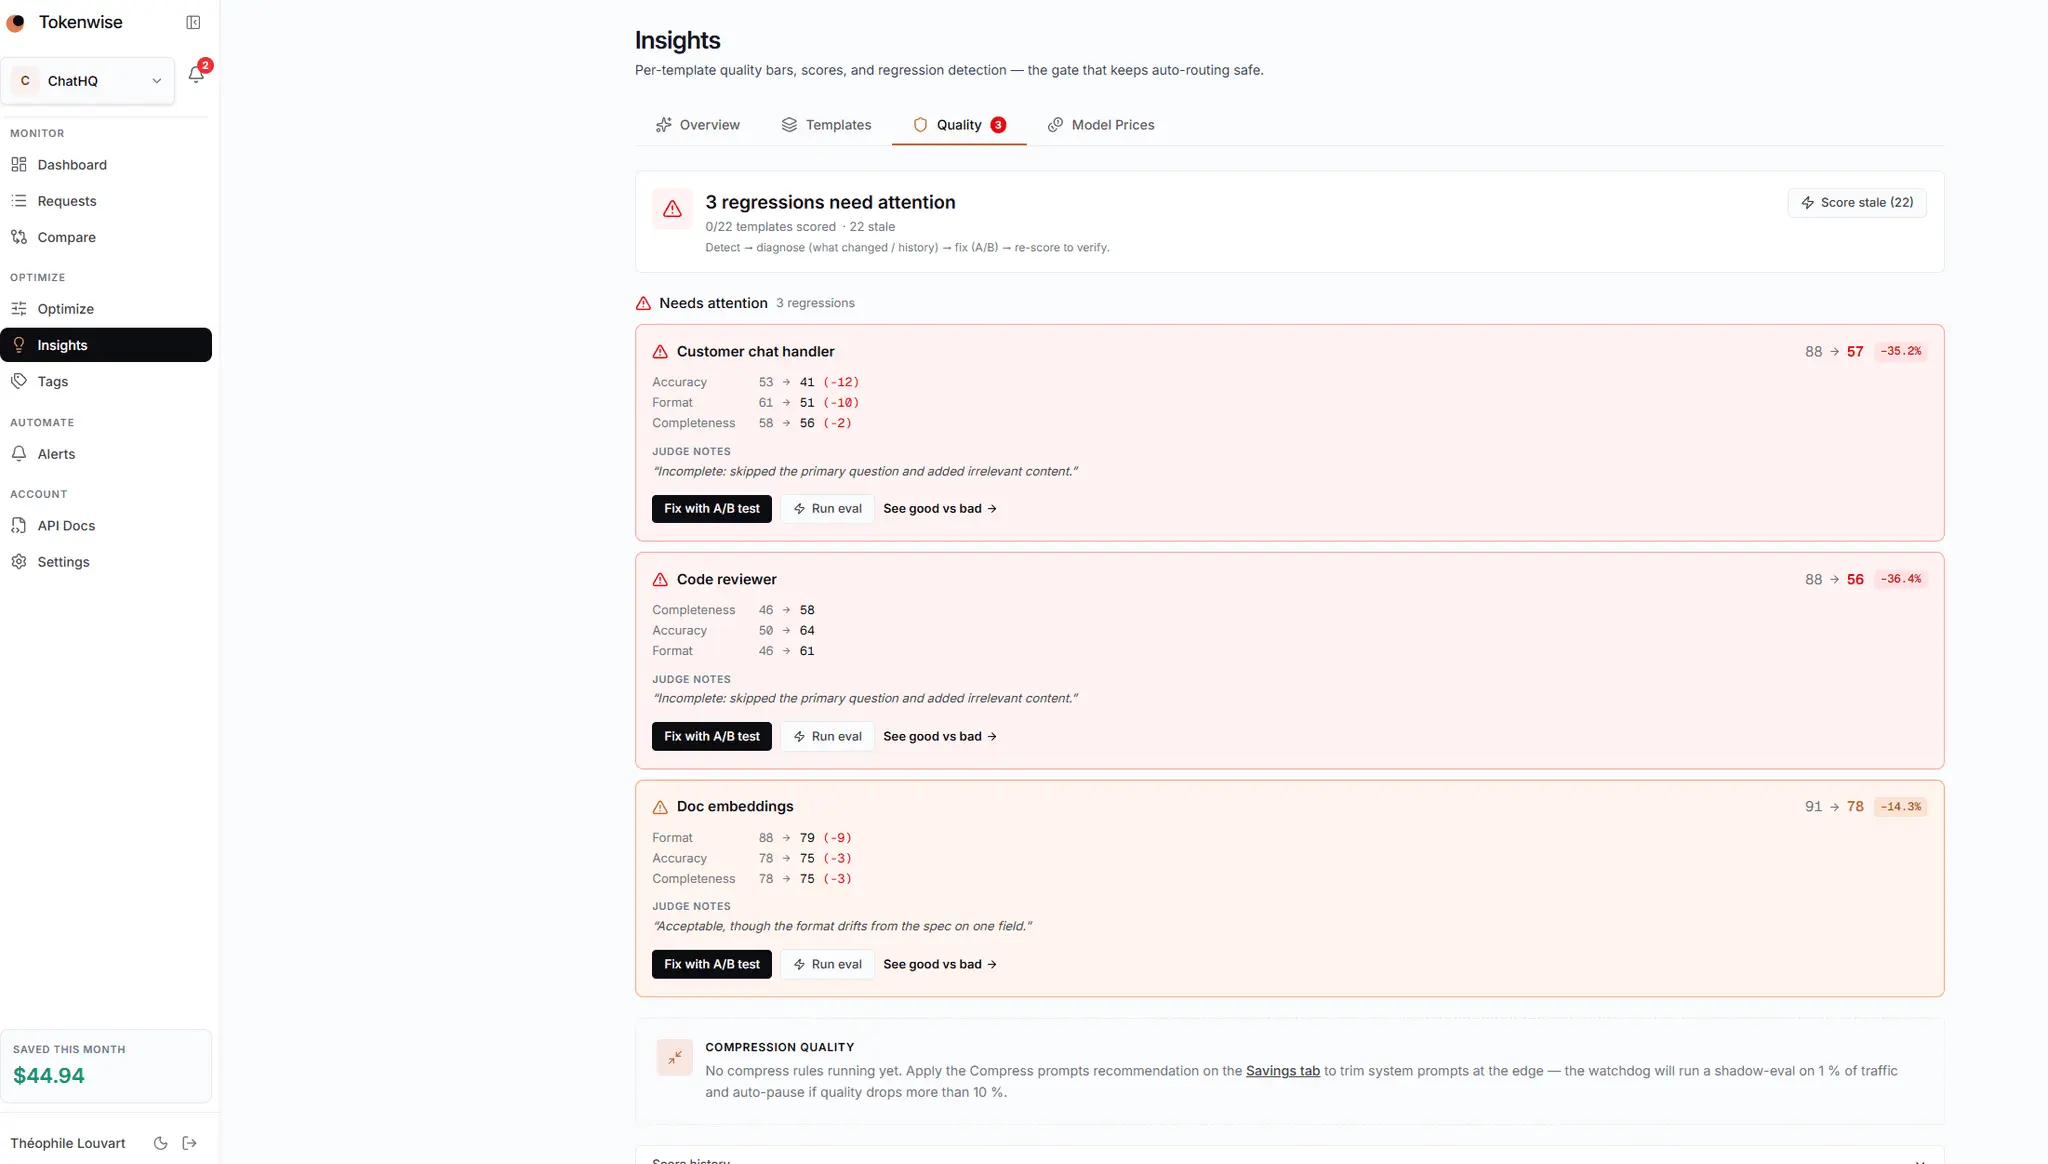
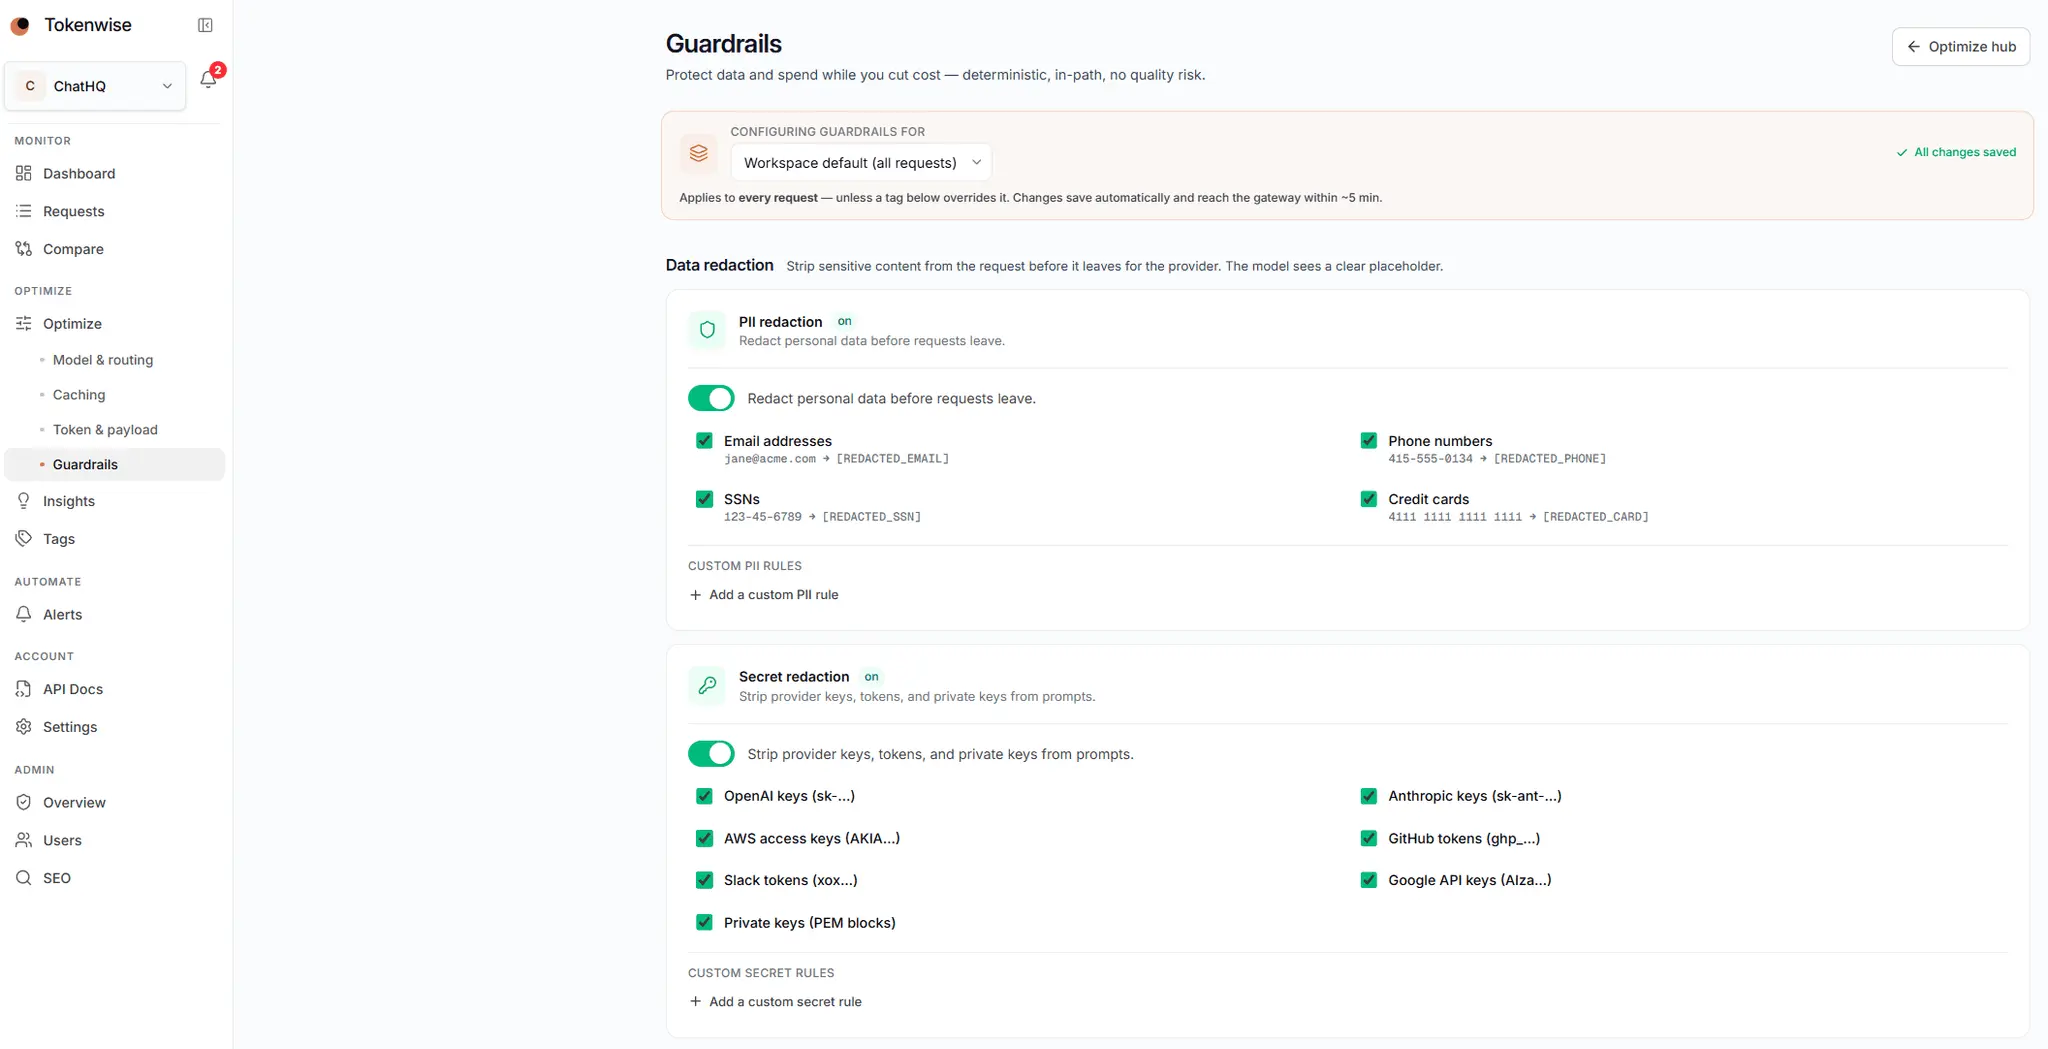
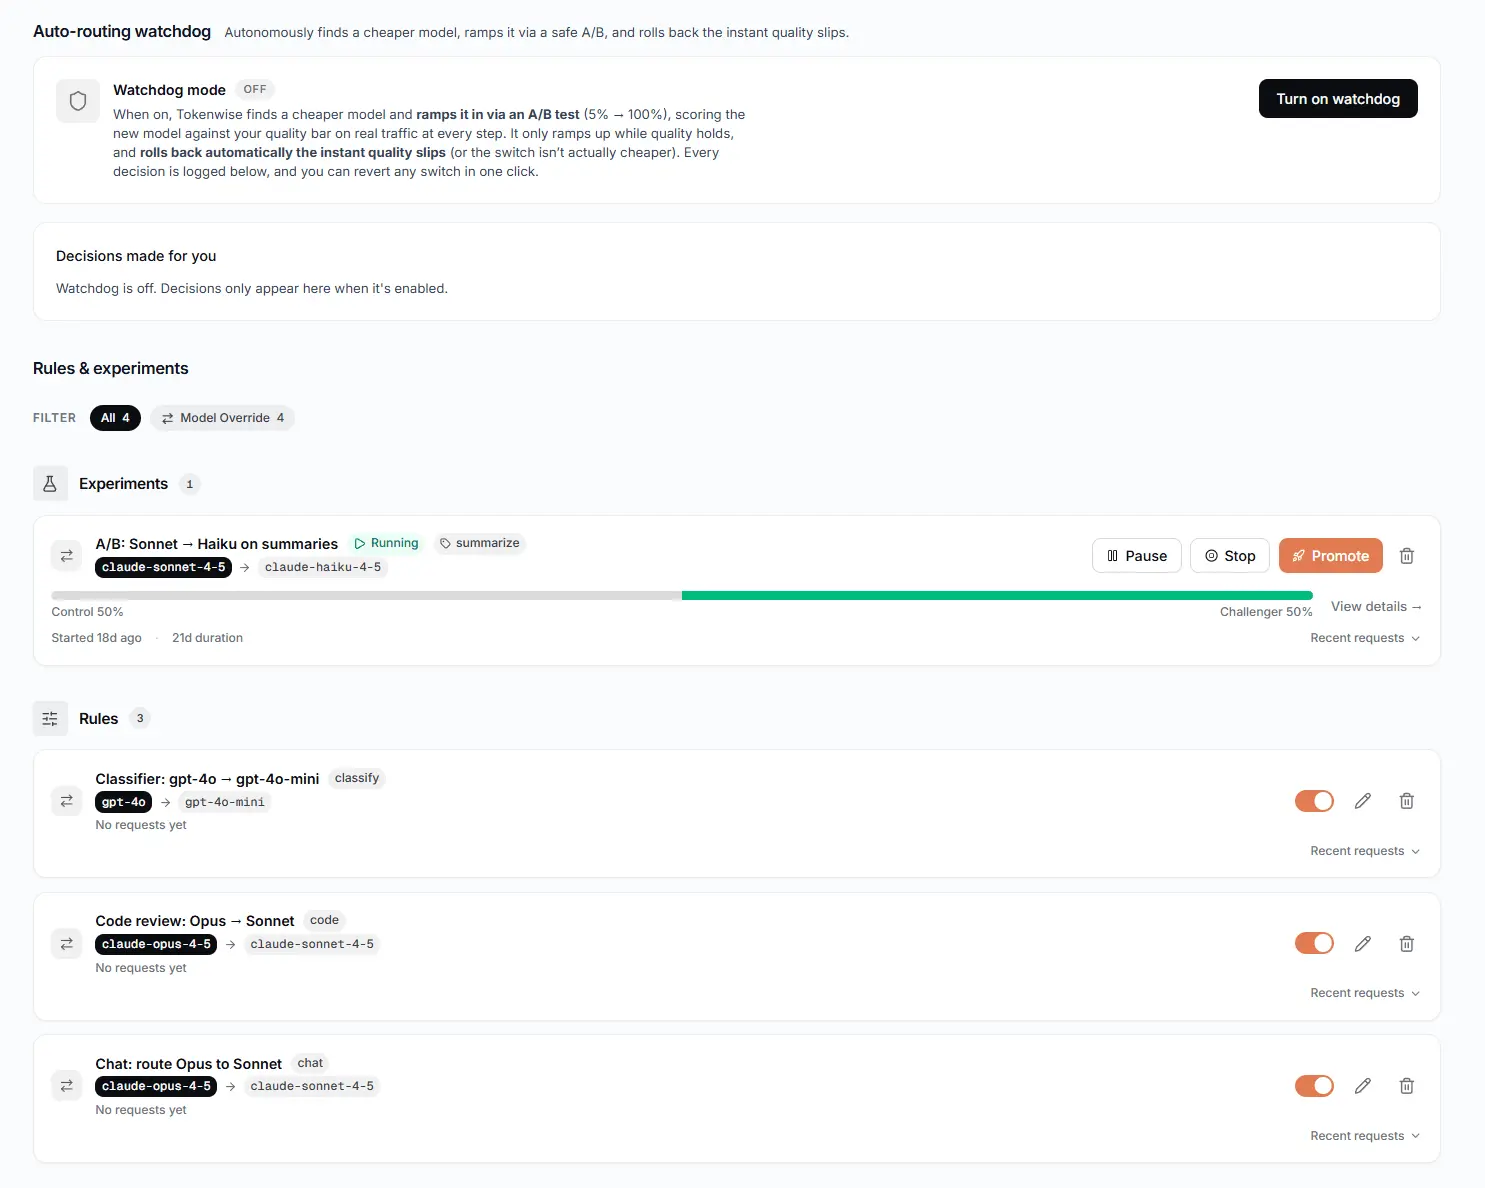
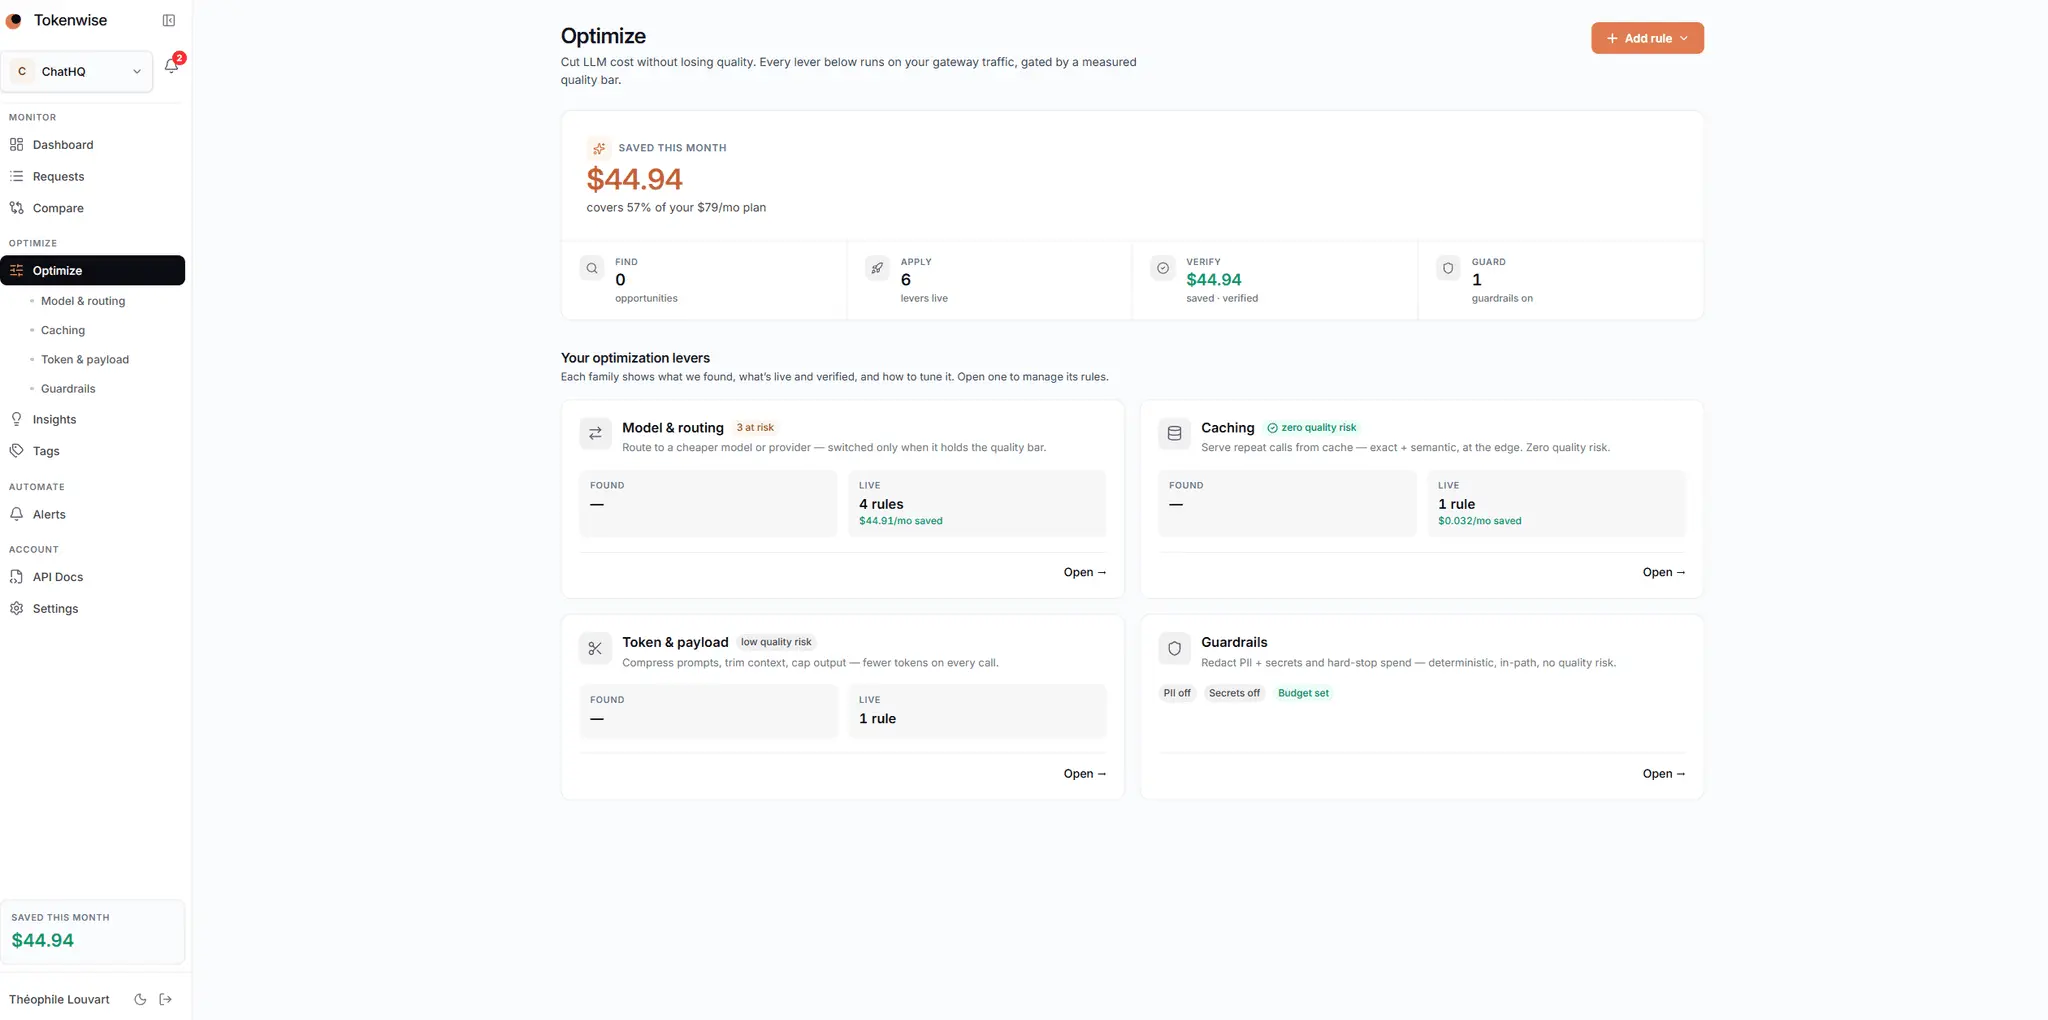
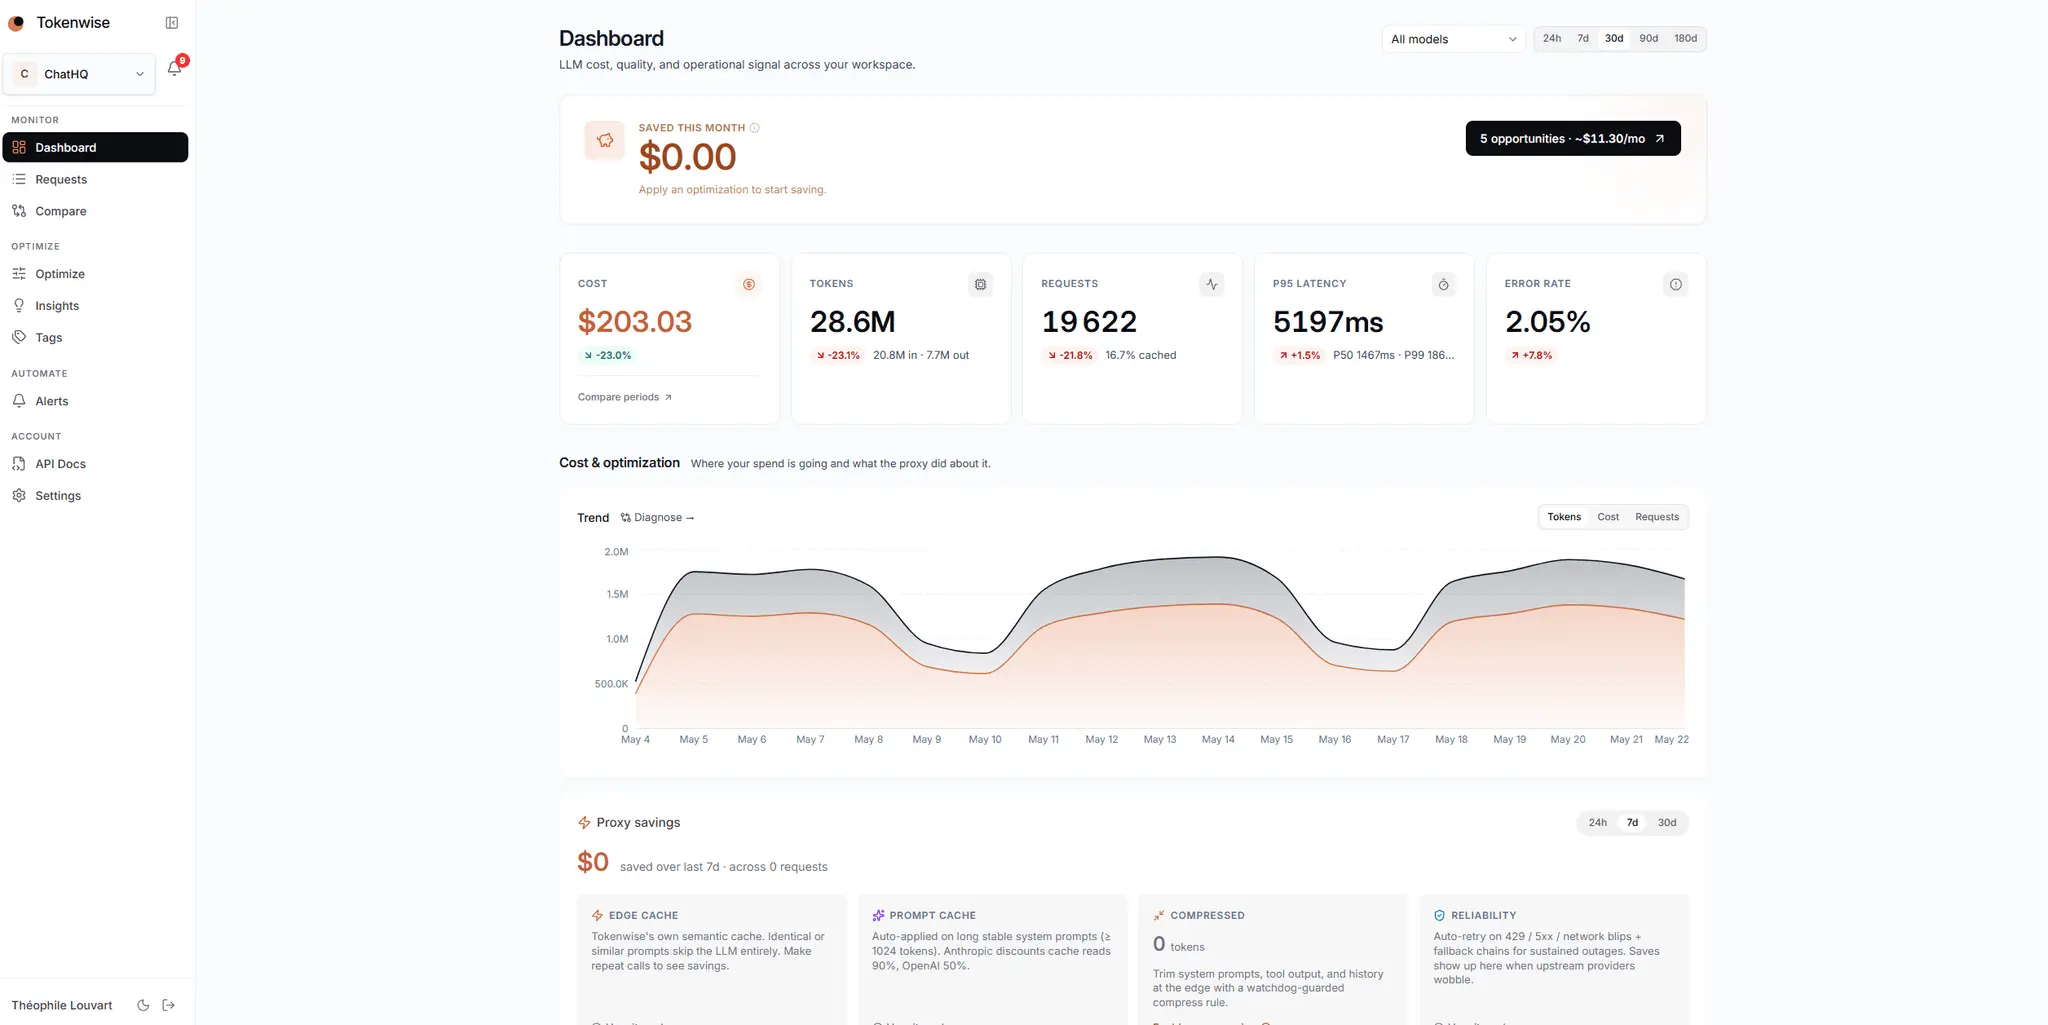
Tokenwise is a one-line LLM proxy (OpenAI-compatible baseURL) for makers and small teams who can never tell where their API bills come from. Add one line of code, or point your coding agents (Claude Code, Cursor, Codex) at it with no production changes, and you see every request: exact re-tokenized cost, input/output tokens, latency, status, model, provider, project, and custom tags. It clusters requests by prompt template so each call type is its own line. Then it acts. It recommends the cut — a cheaper model, a cache, a trimmed prompt — and proves it on your own recent traffic with an LLM judge scored against your rubric, not a public benchmark. Apply in one click as an A/B split, watch quality for 24h, and it auto-rolls-back if quality slips. A live counter tracks the dollars saved. The closed loop — see, then act, then prove quality held — is what makes it more than another dashboard. Free to start, no card required.
Discount Codes
50%(-50% OFF)
Valid until Dec 1, 2026
Screenshots
Reviews (0)
No reviews yet. Be the first to rate this product!
Comments (1)
Maker here. I built Tokenwise because I could never tell which feature or prompt was driving my LLM bill. It shows cost per prompt, cuts it, and proves the savings on your own traffic. Would genuinely